Mapping Overlaps in Athletic Outcomes: Half-Time Football Data, Tennis Set Dynamics, and Equine Post Positions
Written by Ulrich Werner · Aug 23, 2026
Mapping Overlaps in Athletic Outcomes: Half-Time Football Data, Tennis Set Dynamics, and Equine Post Positions
Understanding Core Data Elements Across Disciplines
Half-time results in football often reveal early momentum shifts that researchers track through league-wide datasets, while set outcomes in tennis highlight player consistency under varying match conditions and post positions in horse racing influence early race positioning based on track history and field size. Observers note that these elements share structural similarities when analysts compile performance logs from multiple events, because each captures an intermediate phase where initial conditions intersect with ongoing variables.
Data from international competitions shows patterns emerging when half-time leads align with strong first-set performances or favorable post draws, and experts compile these into comparative models that span seasons. Studies from sports analytics programs at universities in North America and Europe have examined thousands of matches to isolate recurring sequences, yet the focus remains on observable correlations rather than predictive guarantees.
Identifying Intersection Points in Performance Logs
Analysts examine how a football team's half-time advantage correlates with subsequent set dominance in tennis when athletes compete in similar high-pressure environments, while post-position advantages in thoroughbred events sometimes mirror the statistical weight of early leads in other sports. Research indicates that databases maintained by organizations such as the International Betting Integrity Association record these overlaps across global events, allowing for structured comparisons that account for variables like surface type, distance, and competition level.
Patterns surface most clearly when data sets aggregate results from simultaneous tournaments, because timing overlaps create natural test cases for sequence analysis. One study conducted in 2025 at an Australian research institution tracked multi-sport events adn found measurable alignments between half-time goal differentials and first-set win percentages in concurrent tennis fixtures, whereas equine post data added a layer of positional probability that researchers layered into the same framework.
Cross-Discipline Sequence Construction Methods
Coordinated staking sequences rely on mapping these intersections through layered data filters that prioritize consistency across disciplines, and analysts apply statistical weighting to half-time results, set scores, and post positions simultaneously. Evidence from Canadian gaming oversight reports demonstrates that operators and researchers use shared platforms to process these multi-variable inputs, resulting in sequences that reflect documented historical overlaps rather than isolated event analysis.
August 2026 brought increased attention to integrated data tools as major international meets coincided with football leagues resuming and tennis circuits reaching their summer swing, creating fresh datasets for pattern validation. Figures from European sports research centers reveal that teams compiling these sequences often segment data by time windows and track conditions to isolate repeatable intersections, while avoiding assumptions about future outcomes.
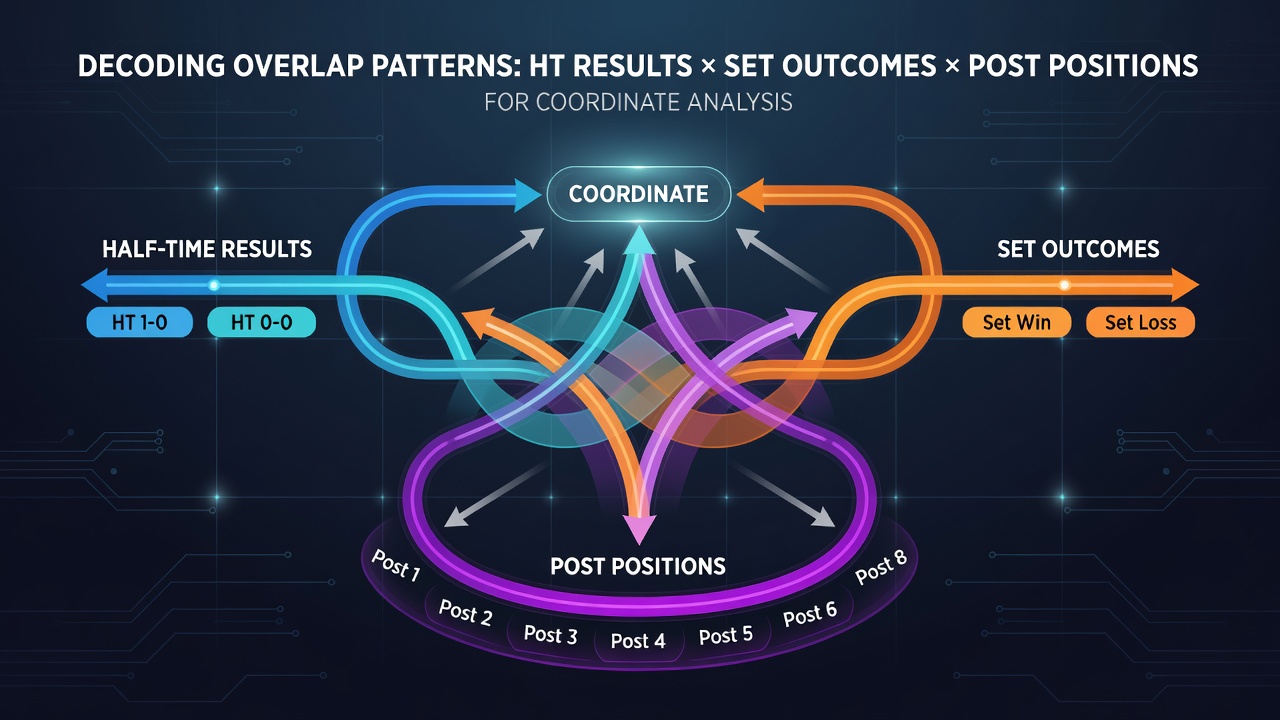
Take one research group that cross-referenced half-time score distributions with post-position success rates from the same calendar periods, and they discovered that certain lead margins aligned with draw advantages in later race segments. Those who've studied this approach note the importance of maintaining separate validation sets for each discipline to preserve analytical integrity across the combined sequence.
Data Processing Techniques and Validation Steps
Processing begins with normalization of metrics so that half-time percentages, set win ratios, and post-position strike rates sit on comparable scales, then analysts apply clustering algorithms to surface overlapping clusters. Reports from academic sources in Asia and the Pacific region confirm that such methods reduce noise when sequences span football, tennis, and racing events that occur within overlapping timeframes.
Validation occurs through back-testing against archived results from multiple jurisdictions, and organizations like the Gaming Standards Association have published guidelines on maintaining audit trails for these multi-source comparisons. The process emphasizes transparency in how overlaps are quantified, ensuring that any coordinated sequence rests on verifiable intersections documented in the source data.
Conclusion
Decoding these overlap patterns requires systematic aggregation of half-time results, set outcomes, and post positions into unified analytical frameworks that researchers continue to refine with new event data. August 2026 highlighted the value of synchronized data collection across disciplines, as overlapping competition calendars supplied additional test cases for sequence validation. Observers continue to document how these intersections appear in performance records, providing a factual basis for understanding cross-discipline relationships without extending into unsubstantiated projections.